
PostgreSQL
Cardinality
In the context of relational databases, cardinality refers to the uniqueness of data values contained in a particular column (attribute) of a table. Cardinality is important for understanding the relationships between tables and for optimizing database queries. High cardinality means a column has many unique values, while low cardinality means it has fewer unique values.
In PostgreSQL, cardinality plays a crucial role in designing efficient database schemas and queries. Let's dive into how cardinality affects table design, especially for banking systems.
- Understanding Cardinality
- High Cardinality: Columns with many unique values. For example, an account number column in a banking table will have high cardinality because each account number is unique.
- Low Cardinality: Columns with fewer unique values. For instance, a column indicating account status (Active, Inactive) will have low cardinality because it only contains a few possible values.
- Creating Tables with Cardinality Considerations
- Customers Table: High cardinality on customer ID.
- Accounts Table: High cardinality on account number.
- Transactions Table: High cardinality on transaction ID.
-- Create Customers Table CREATE TABLE Customers ( customer_id SERIAL PRIMARY KEY, -- High Cardinality name VARCHAR(100) NOT NULL, email VARCHAR(255) UNIQUE ); -- Create Accounts Table CREATE TABLE Accounts ( account_number BIGINT PRIMARY KEY, -- High Cardinality customer_id INT REFERENCES Customers(customer_id), balance DECIMAL(10, 2) NOT NULL ); -- Create Transactions Table CREATE TABLE Transactions ( transaction_id SERIAL PRIMARY KEY, -- High Cardinality account_number BIGINT REFERENCES Accounts(account_number), transaction_date TIMESTAMP DEFAULT CURRENT_TIMESTAMP, amount DECIMAL(10, 2) NOT NULL ); - Indexing for High Cardinality
- Indexing helps in faster query processing for high cardinality columns. PostgreSQL automatically creates an index on primary keys, but additional indexing might be needed for non-primary columns used in queries.
-- Create an Index on Account Number for Fast Lookup
CREATE INDEX idx_account_number ON Accounts(account_number);
- Indexing helps in faster query processing for high cardinality columns. PostgreSQL automatically creates an index on primary keys, but additional indexing might be needed for non-primary columns used in queries.
- Analyzing Cardinality
- Use PostgreSQL’s
ANALYZEcommand to collect statistics about column values, which helps in query optimization.-- Analyze the Customers Table ANALYZE Customers;
- Use PostgreSQL’s
By understanding and leveraging cardinality, you can design more efficient schemas and optimize queries for better performance in PostgreSQL.
1:1 Relationship
A1:1 (one-to-one) relationship between two tables occurs when each record in the first table is related to only one record in the second table, and vice versa. This relationship is often used to extend a table or to store sensitive data separately.
Example: User and User Profile
In an application, each user has a single user profile, and each user profile is associated with a single user.
- Users table:
UserID,Username,Email - UserProfiles table:
ProfileID,UserID(foreign key),Address,PhoneNumber
SQL Example:
CREATE TABLE Users (
    UserID INT PRIMARY KEY,
    Username VARCHAR(255) NOT NULL,
    Email VARCHAR(255)
);

CREATE TABLE UserProfiles (
    ProfileID INT PRIMARY KEY,
    UserID INT,
    Address VARCHAR(255),
    PhoneNumber VARCHAR(255),
    FOREIGN KEY (UserID) REFERENCES Users(UserID)
);
1:N Relationship
A1:N (one-to-many) relationshipbetween two tables occurs when a single record in the first table can be associated with one or more records in the second table. This is the most common relationship type.
Example: Author and Books
An author can write several books, but each book has only one author.
- Authorstable:
AuthorID,Name,Country - Bookstable:
BookID,Title,PublicationYear,AuthorID(foreign key)
SQL Example:
CREATE TABLE Authors (
    AuthorID INT PRIMARY KEY,
    Name VARCHAR(255) NOT NULL,
    Country VARCHAR(255)
);

CREATE TABLE Books (
    BookID INT PRIMARY KEY,
    Title VARCHAR(255) NOT NULL,
    PublicationYear INT,
    AuthorID INT,
    FOREIGN KEY (AuthorID) REFERENCES Authors(AuthorID)
);
Many-to-One (N:1)
AN:1 relationship is the inverse of 1:N, where many rows in Table A relate to a single row in Table B. It's another perspective of viewing a 1:N relationship, focusing on how multiple instances relate to a single instance on the other side.
Many-to-Many (N:N)
AN:Nrelationship occurs when rows in Table A can relate to many rows in Table B and vice versa. This type of relationship requires a third table, known as a junction or join table, to manage the associations between the entities.
Example Diagrams and Implementations:
Entity-Relationship Diagrams (ERDs) are often used to visually represent these relationships, with symbols indicating the type of cardinality between tables.
For example, in a library system, an Authors table and a Books table would have a 1:N relationship (one author can write multiple books), while a Users table and UserProfiles table might have a 1:1 relationship (each user has one profile).
SAMPLE DATA MODEL FOR 1:N (one-to-many)
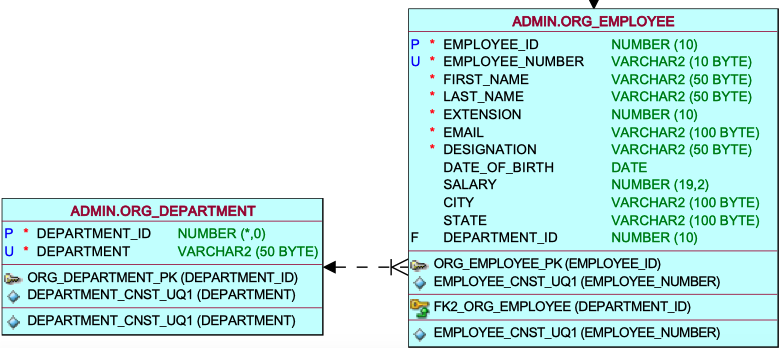
As evident in the data model, the relationship line connecting the department and employee tables illustrates a one-to-many relationship—where one instance exists on the department side and multiple instances on the employee side. This signifies that within the department table, a given department may have zero, one, or multiple occurrences in the employee table. For instance, department ID 1 is utilized once in the employee table, department 2 is used multiple times, and department 5 is not utilized at all in the employee table.
Comments Not Found